Letting Data Speak, AI Act!
Case Study
Data ScienceAI-Powered Utility Bill Processing
Overview
JashDS designed and deployed a serverless, event-driven utility bill processing pipeline on AWS to solve three critical gaps: eliminating error-prone manual PDF data entry, reconciling extracted data against existing API records, and providing a structured escalation path for exceptions. The solution leverages Claude Sonnet 4 via Amazon Bedrock with tiered confidence scoring, AWS Lambda for reconciliation and review logic, HubSpot for human-in-the-loop corrections, and Amazon QuickSight for real-time operational visibility — achieving 95%+ extraction accuracy, processing each document in under 60 seconds at approximately $0.01 per PDF, and ensuring zero data loss across all document types.
About the Client
A utility bill management organization that processes high volumes of bills across diverse providers, relying on accurate bill data to drive downstream financial workflows for its users.
The Challenge
Utility bill PDFs arrived from dozens of providers, each with different layouts, fonts, and field structures. The organization had no automated system to extract, validate, or reconcile bill data, leaving staff to process every document by hand. Three core problems demanded a solution:
- Manual Data Extraction
- No Data Reconciliation
- No Error Handling or Escalation Path
Manual Data Extraction
No automated system existed to extract key bill fields — provider name, account number, due date, and amount due — from uploaded PDFs. Staff processed each document by hand, creating backlogs and data quality issues as volumes grew.
No Data Reconciliation
For accounts where bill data already existed from API integrations, there was no mechanism to compare newly extracted PDF data against existing records. Conflicting values went undetected and missing fields were never auto-filled.
No Error Handling or Escalation Path
When extraction quality was uncertain — due to corrupted files, low-resolution scans, or ambiguous content — there was no structured escalation path. Failed documents were simply lost with no archival, logging, or retry logic in place.
Key Results
Extraction Accuracy & Speed
- Achieved 95%+ data extraction accuracy through a tiered confidence scoring system (1.0 for critical fields, 0.8 for secondary fields).
- Reduced bill document processing time to under 60 seconds per PDF, replacing the fully manual data entry workflow and eliminating processing backlogs.
Reliability & Cost
- Eliminated data loss through six categorised error types with automatic S3 archival, error metadata logging, and exponential-backoff retry logic.
- Deployed a cost-effective serverless architecture processing documents at approximately $0.01 per PDF, with auto-scaling that absorbed volume spikes without infrastructure changes.
- Delivered a fully integrated human-in-the-loop HubSpot review workflow — corrections written back to the database automatically upon ticket closure via webhook, requiring no additional manual steps.
Our Solution
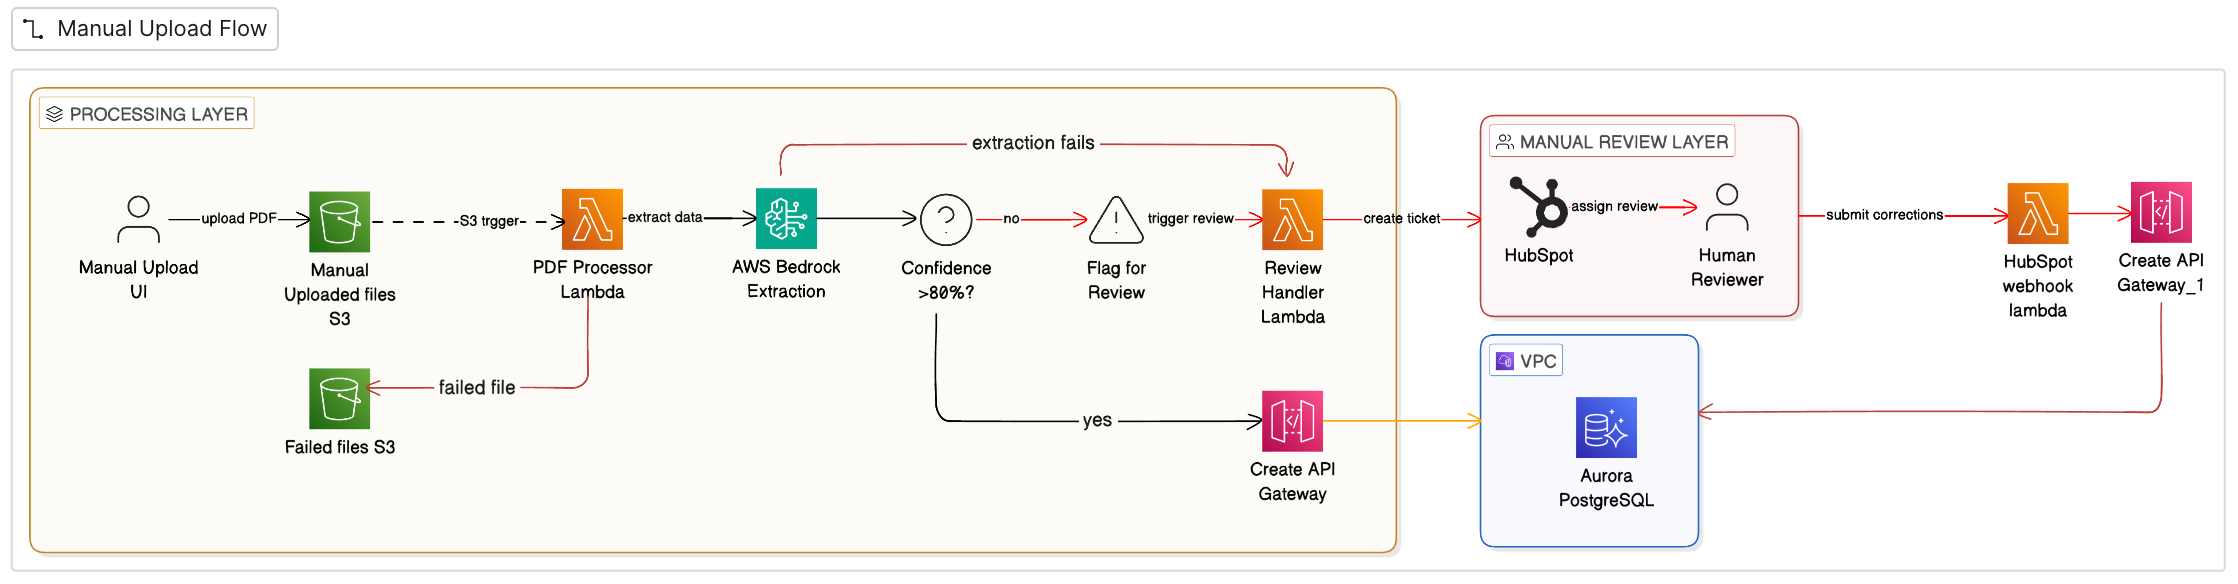
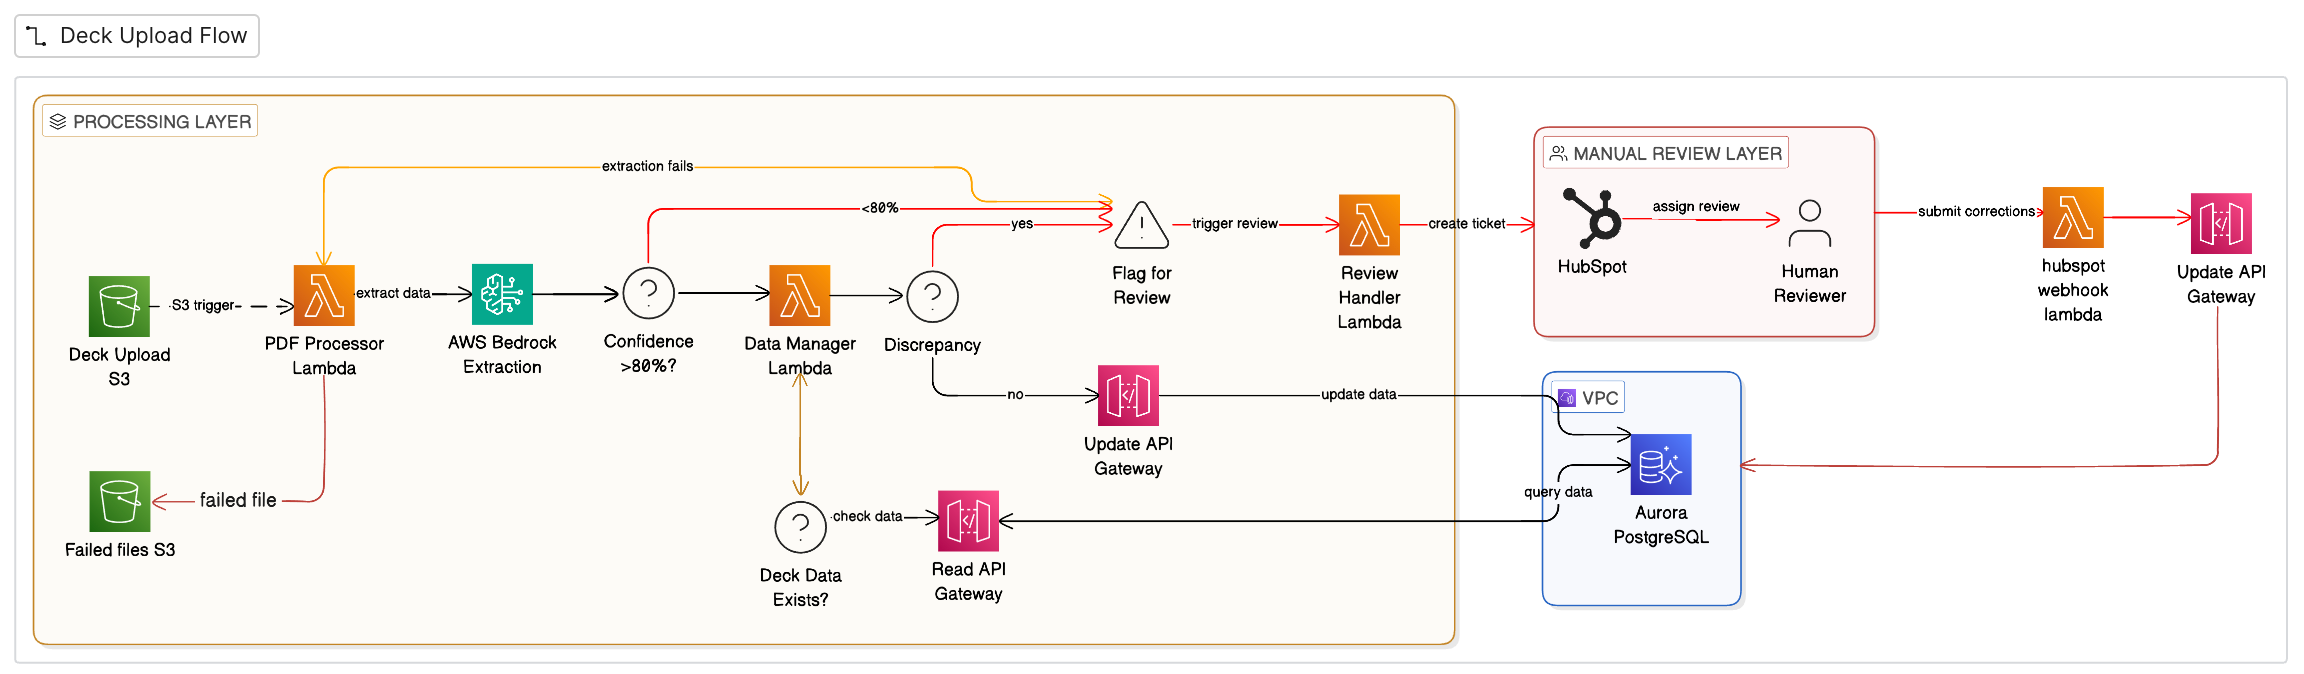
The JashDS team designed and deployed a fully serverless, event-driven utility bill processing pipeline on AWS. The system automated the complete lifecycle — from PDF ingestion through AI extraction, intelligent data reconciliation, and human-in-the-loop review — with no manual intervention required for standard-quality documents.
Key Components:
- Ingestion Layer: Dual-path S3 event-driven ingestion — manual uploads write directly to the database; batch uploads route through reconciliation before any writes
- AI Extraction Layer: AWS Bedrock with Claude Sonnet 4 returning per-field confidence scores (0.0–1.0); Amazon Nova Pro as automatic fallback model
- Reconciliation Layer: AWS Lambda with type-aware field comparison — decimal precision for monetary amounts, date normalisation, case-insensitive string matching
- Review Layer: HubSpot-integrated ticketing with webhook handler that writes reviewer corrections back to Aurora PostgreSQL on ticket closure
Observability Layer: Amazon QuickSight dashboard connected via private VPC to Aurora PostgreSQL — surfacing active bills, overdue amounts, biller performance, and reviewer workload in real time
Technologies Used
Related Case Studies
← Back to All Case Studies
Data Science
AI-Assistance for Customer Support for Rent-to-Own Industry
A rent-to-own industry organization struggled with inconsistent customer support quality and slow response times that impacted lead conversion rates. By implementing an AI-powered chat assistance system using AWS Bedrock and retrieval-augmented generation, the organization enabled agents to receive three context-aware response suggestions within seconds during live conversations. The solution leverages historical successful conversations through semantic search and Claude Haiku 4.5, ensuring every agent delivers high-quality, proven communication strategies regardless of experience level. The serverless architecture processes thousands of requests monthly while maintaining reliability through intelligent fallback mechanisms and comprehensive monitoring.
Read More
Data Science
Artificial Intelligence - Driven Candidate Screening Revolution
JashDS revolutionized a company's hiring process by developing a GenAI-powered candidate screener that reduced time-to-hire by 50% and improved hiring outcomes. The solution leverages advanced language models to conduct dynamic, role-specific interviews, automatically generating and adapting questions based on job descriptions and candidate responses.
Read More
Data Science
Artificial Intelligence Model for Retail Shelf Monitoring
JashDS revolutionized retail shelf management for a major grocery chain by developing an AI-powered real-time monitoring system. The solution utilized advanced computer vision techniques and deep learning models to detect out-of-stock and misplaced products, significantly improving inventory accuracy and enhancing the customer shopping experience while reducing manual labor costs.
Read MoreHave a similar challenge?
Connect with us