Letting Data Speak, AI Act!
Case Study
Data ScienceAI-Powered Misconception Detection for Science Education
Overview
An education technology company needed to automate the generation of misconception-aware, grade-appropriate feedback for K-12 science assessments at scale, replacing a manual process that could not keep pace with content demand. A serverless, AI-powered system leveraging AWS Lambda, Amazon Bedrock with Claude Sonnet 4.5, and tool-enforced structured output was deployed, enabling automated feedback generation at approximately $0.016 per question with 100% schema-validated consistency across all grade levels.
About the Client
An education technology company focused on improving science instruction across K-12 grade levels. The organization required a scalable, automated system to deliver high-quality, pedagogically aligned feedback for multiple-choice science assessments, supporting consistent academic outcomes for students ranging from kindergarten through high school.
The Challenge
The client faced a critical gap in delivering personalized, misconception-aware feedback for science questions at scale. Traditional approaches to generating instructional feedback relied on manual content creation by subject-matter experts, which was time-intensive, inconsistent across grade levels, and difficult to scale across a growing question bank.
- Inconsistent feedback quality: Manually authored feedback varied in tone, depth, and pedagogical alignment, resulting in uneven learning experiences for students across different grade bands (K-2, 3-5, 6-8, 9-12).
- Inability to scale: As the volume of science questions expanded, the manual feedback pipeline became a bottleneck, preventing timely deployment of new assessment content.
- Lack of misconception targeting: Existing feedback mechanisms did not systematically identify and address the specific scientific misconceptions behind each incorrect answer option, limiting instructional effectiveness.
- Grade-level adaptability: Producing feedback with vocabulary, sentence structure, and explanation depth appropriate to each grade band required significant manual effort per question, further slowing content production.
Without an automated solution, the client risked degraded educational outcomes, slower content velocity, and an inability to support the growing demand for high-quality, adaptive science instruction.
Key Results
- Reduced feedback generation time from hours of manual authoring to approximately 1.6 cents per question (~$160.50 per 10,000 requests), enabling near-real-time, cost-effective content production at scale.
- Achieved structured, schema-validated feedback output for every question processed, ensuring 100% consistency in format and pedagogical alignment across all grade levels (K-2, 3-5, 6-8, 9-12).
Our Solution
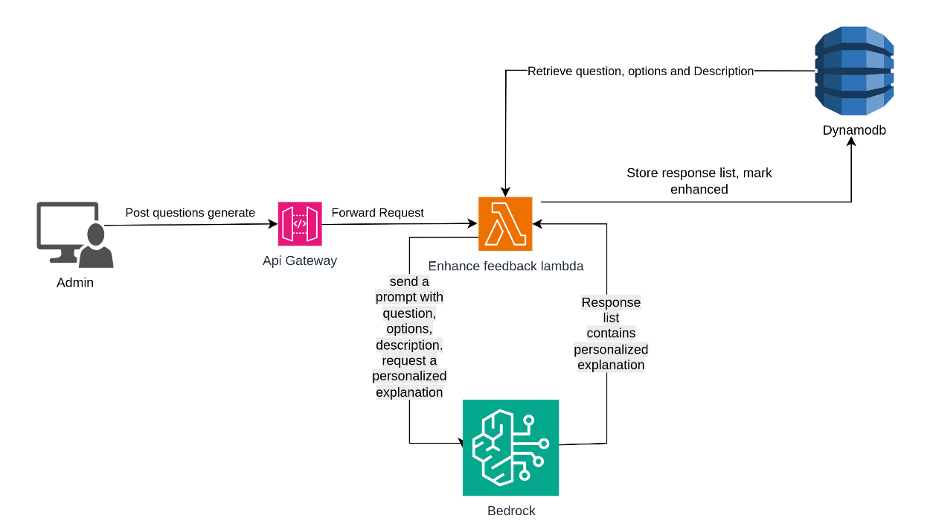
The solution was a serverless, API-driven system built entirely on AWS managed services, centered around a single AI-processing Lambda function responsible for end-to-end feedback generation.
- API-driven intake: A secure REST API endpoint was exposed via Amazon API Gateway, accepting structured question payloads (question text, answer options, correct answer, and grade level) with API key authentication and JSON validation.
- Deterministic question identification: Each incoming question was assigned a unique, reproducible identifier using SHA256 hashing, enabling deduplication and efficient retrieval of previously generated feedback from Amazon DynamoDB.
- Grade-aware prompt engineering: The Lambda function dynamically constructed instructional prompts with grade-level vocabulary control, sentence structure rules, writing constraints, and forced explanation opener rotation to ensure age-appropriate, pedagogically sound output.
- AI model integration with structured output enforcement: Claude Sonnet 4.5 was invoked via Amazon Bedrock with tool-based structured output enforcement and strict JSON schema validation. Temperature was set to 0.3 for deterministic, consistent responses, with a 3,000-token output limit. Additional controls prevented answer leakage, analogy usage, and formatting inconsistencies.
- Misconception-targeted feedback: For each incorrect answer option, the system generated a specific misconception label, a correct scientific principle, and a detailed, empathetic explanation addressing why the student may have chosen that answer and guiding them toward accurate understanding.
- Infrastructure as Code deployment: The entire infrastructure was provisioned and managed using Terraform, with remote state stored in S3 and state locking via DynamoDB to prevent concurrent deployment conflicts. The deployment pipeline supported reproducible, environment-specific rollouts.
- Robust error handling: Input validation, schema enforcement on model output, structured HTTP error responses, and comprehensive try-except logging ensured system resilience and clear diagnostics.
Technologies Used
Related Case Studies
← Back to All Case Studies
Data Science
AI-Assistance for Customer Support for Rent-to-Own Industry
A rent-to-own industry organization struggled with inconsistent customer support quality and slow response times that impacted lead conversion rates. By implementing an AI-powered chat assistance system using AWS Bedrock and retrieval-augmented generation, the organization enabled agents to receive three context-aware response suggestions within seconds during live conversations. The solution leverages historical successful conversations through semantic search and Claude Haiku 4.5, ensuring every agent delivers high-quality, proven communication strategies regardless of experience level. The serverless architecture processes thousands of requests monthly while maintaining reliability through intelligent fallback mechanisms and comprehensive monitoring.
Read More
Data Science
AI-Powered Knowledge Access Platform for Rent-to-Own Industry
A rent-to-own industry organization struggled with fragmented information access across public industry knowledge bases and private operational databases, forcing users to manually search multiple systems and preventing timely, data-driven decision-making. By implementing a dual-pipeline RAG architecture with AWS Bedrock, Amazon OpenSearch, and intelligent query routing, the solution reduced knowledge base query response times to 5-8 seconds and enabled natural language access to both public and private data sources through a unified conversational interface powered by Claude Sonnet 4 and Titan Embeddings v2.
Read More
Data Science
AI Driven Course Curriculum Map Generation and Searching System
A fully accredited nonprofit medical school automated its curriculum mapping process using an AI-driven system on AWS. The solution processed 22+ courses end-to-end — from raw IMSCC files to prerequisite-aware, AAMC-aligned curriculum maps — significantly reducing manual effort and improving consistency across its medical education program.
Read MoreHave a similar challenge?
Connect with us